In just a few decades, genomics has progressed from sequencing a single viral genome to decoding the genetic diversity of entire populations.1 Today, researchers are identifying the genetic basis of rare diseases, uncovering hereditary cancer risk buried in an individual’s genome, and tracking pathogen evolution across continents. These endeavors provide insights that were unimaginable when the very first genomes were decoded.2,3
Though as scientific ambition grows, so do the technical demands. Large-scale genomic projects require platforms that generate vast amounts of high-quality data with rapid turnaround. For many laboratories, the challenge is no longer whether sequencing can answer a biological question, but how to efficiently generate and analyze data to meet demands. Advances in sequencing technology help remove these barriers, bringing powerful genomic analysis to a wider range of research environments.
The Growing Demand for High-Resolution Genomics
To better understand complex biological systems and advance modern research, scientists increasingly seek a more comprehensive view of genomes, transcriptomes, and epigenetic features.
Long-read sequencing has become an essential tool in this effort. By reading DNA and RNA molecules across much greater lengths than conventional short-read approaches, long-read technologies can simplify genome assembly, improve structural variant detection, and characterize transcript isoforms. These approaches sequence native DNA and RNA directly without amplification, meaning they can also capture methylation and other base modifications alongside the underlying sequence without additional sample prep or separate sequencing runs.
However, generating richer datasets also increases computational demands. High-throughput sequencing projects can produce substantial data requiring efficient processing, analysis, and interpretation. For many labs, managing this workflow can become a bottleneck.
When Sequencing Outpaces Infrastructure
Historically, researchers seeking higher sequencing output often faced the challenge of securing the computing resources to handle the resulting data.
This can be particularly problematic for smaller research groups, translational laboratories, and emerging genomics programs, as the supporting infrastructure—from dedicated workstations and graphics processing units to data storage and bioinformatics resources—can incur substantial spatial and financial costs.
As a result, some laboratories find themselves balancing ambitious research goals against practical limitations.

PromethION™ 2 Integrated: High Output in a Compact Package
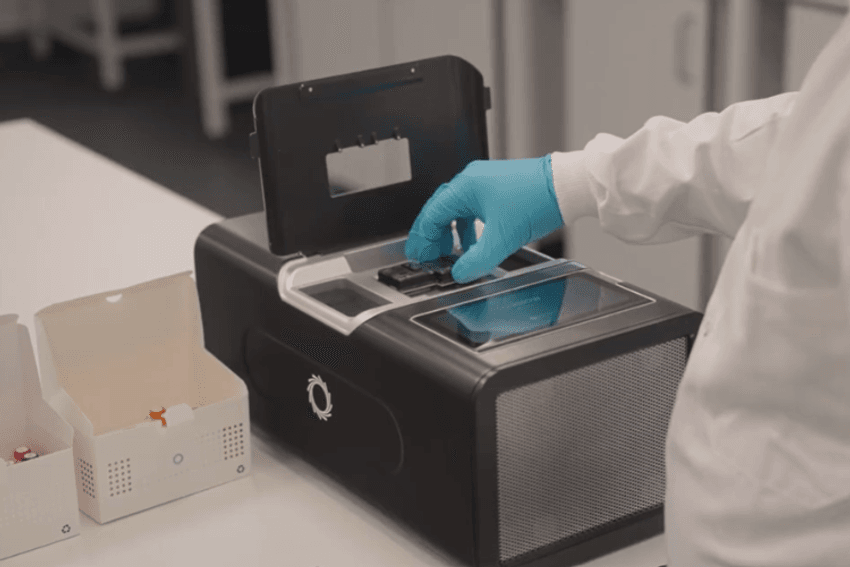
To address these challenges, Oxford Nanopore Technologies developed the PromethION™ 2 Integrated, a compact benchtop sequencing device that combines high-output nanopore sequencing with onboard computing and analysis capabilities. Designed for researchers tackling increasingly ambitious genomic studies, the PromethION 2 Integrated delivers the throughput needed for large-scale sequencing projects without the infrastructure demands traditionally associated with high-output platforms. The any-read length system supports lengths from short fragments to ultra-long reads (20bp to >4Mb), enabling applications including human and large genome sequencing, metagenomics, transcriptomics, and targeted sequencing workflows.
The fully integrated device runs two independent PromethION flow cells, enabling laboratories to advance separate projects simultaneously, perform different applications on each flow cell, or scale sequencing output according to changing demands. Furthermore, unlike systems requiring separate computational infrastructure, the PromethION 2 Integrated features high-performance onboard processing, enabling researchers to generate and analyze data directly on a single platform. For instance, by leveraging the device’s capabilities, researchers generated acute leukemia classification predictions from real-time methylation data within 10 minutes of sequencing, highlighting the potential for rapid, actionable insights during data generation.
To further reduce data analysis burdens, researchers can leverage Adaptive Sampling, Oxford Nanopore’s software-driven targeted sequencing technology, which selects and sequences specific regions of interest in real time. By analyzing DNA molecules as they enter the nanopore, Adaptive Sampling determines whether a read belongs to a target region of interest. Off-target molecules are selectively ejected from the pore, focusing sequencing capacity on relevant sequences and reducing off-target data generation. As target selection happens computationally rather than in a wet lab, enrichment panels can be designed and updated in software, without the lengthy optimization wet-lab approaches typically require.
Overall, PromethION 2 Integrated enables users to monitor run performance, obtain early experimental insights, and make informed decisions before completion.
Bringing Big-Picture Genomics to More Labs
As genomic research continues to advance, successful laboratories require tools that deliver both performance and accessibility. By combining high-output nanopore sequencing, real-time analysis, built-in gold-standard methylation calling, and integrated computing within a benchtop system, PromethION 2 Integrated helps bring advanced genomic capabilities to more labs. Whether investigating human disease or conducting large-scale multiomic studies, users can now access PromethION-scale sequencing power in a streamlined format designed for the modern laboratory.
Oxford Nanopore Technologies, the Wheel icon, and PromethION are registered trademarks or the subject of trademark applications of Oxford Nanopore Technologies plc in various countries. Information contained herein may be protected by copyright, patents or patents pending of Oxford Nanopore Technologies plc. Oxford Nanopore Technologies products are RUO. Products labelled/branded as Oxford Nanopore Diagnostics may be RUO or may be regulated as in‐vitro diagnostic devices in some jurisdictions, please check individual product labelling.
- Bergström A, et al. Insights into human genetic variation and population history from 929 diverse genomes. Science. 2020;367:eaay5012.
- Sinha S, et al. Long-read sequencing enhances pathogenic and novel variation discovery in patients with rare diseases. Nat Commun. 2025;16:2500.
- Nabeshima K, et al. Draft genome sequence data of Indian rhinoceros, Rhinoceros unicornis. Data Brief. 2022;41:107857.